Lossless Lidar Compression at Fleet Scale
At LatentWorlds we help companies ingest, store and process sensor data at petabyte scale. A single self-driving test vehicle records about 480 GB of uncompressed camera, radar and lidar data per hour of driving, and our customers keep these recordings for years to reproduce incidents, run regression tests and train models. Storage is a major recurring cost that grows with every vehicle and hour driven, and lidar is the largest share. Some uses tolerate lossy compression, and many need the original data bit for bit. This article covers lossless lidar compression and the LatentWorlds codec as of September 2026.
How the data breaks down
Lidar and cameras produce nearly all of a vehicle’s sensor data. Measured as uncompressed message data, lidar accounts for about 68% of this recording and cameras for about 27%, while radar, IMU, GNSS, CAN and transforms together make up the remaining 5% (Figure 2). The split follows from what each sensor hands the recorder. The cameras here deliver JPEG frames that are already compressed, as do the cameras in public driving datasets such as nuScenes, Waymo Open and Argoverse 2. A 128-beam lidar delivers raw measurements, about 1.3 million points per second, each with three 32-bit float coordinates plus timestamps and intensity channels. Fleets that record cameras as H.264 or H.265 video reduce camera data by roughly another 8× (measured on this recording’s three cameras), which would raise lidar’s share to about 89%.
That share tends to grow with each sensor generation, because the data rate scales with beam count, column count and frame rate, and vehicles often carry more than one lidar. Storage cost therefore follows the lidar configuration more closely than any other part of the sensor suite.
| Sensor | Share | MB/s | GB/hour |
|---|---|---|---|
| Lidarthe lidar scan and the localization cloud built from it | 68% | ~90 | ~320 |
| Camera3 cameras at about 24 Hz, already JPEG | 27% | ~36 | ~130 |
| Radar | 1.6% | ~2.1 | ~7.6 |
| IMU, GNSS, odometry | 0.20% | ~0.27 | ~0.96 |
| CAN and vehicle | 0.10% | ~0.13 | ~0.48 |
| TF and othertransforms, diagnostics, everything else | 2.7% | ~3.5 | ~13 |
Anatomy of a lidar point
The lidar in this recording is a 128-beam spinning sensor made by Ouster. For each point it reports a position, the measured range, three intensity channels, the firing time and the beam index, 28 bytes of declared fields in all. Perception, motion compensation and calibration each depend on different parts of that record, so a codec for stored recordings has to keep all of it.
- x, y, z: the point in the sensor frame, as 32-bit floats. They are computed from range and the beam’s fixed direction, so the decoder can rebuild them instead of storing them (section 9).
- t: the firing time of the column. The sensor sweeps for 100 ms per turn while the vehicle moves, and motion compensation uses t to place each point where it was measured.
- ring: the beam index, which gives each point its row in the scan.
- range: the measured distance in millimetres, the quantity the sensor actually observes.
- signal, reflectivity, near_ir: return strength, range-corrected surface brightness and ambient infrared light. Perception uses them for lane markings, signs and materials; calibration and health checks use their statistics.
The recording also holds a second lidar topic built from the same sensor, the localization cloud. Its points are motion-corrected and no longer in scan order, and each carries only a position, an intensity and a label, 20 bytes in all (Figure 3).
Why lossless
This report is limited to lossless compression. Uses that can accept a loss of precision, such as visualisation, coarse mapping and streaming previews, are served well by lossy codecs, and a separate report will cover them.
For the workloads below, exactness is a hard requirement, because they depend on the exact bytes the sensor produced.
- Replay and regression testing: a re-run on a recording isolates a software change only if the input is identical, since one changed bit can change a detection or a trajectory.
- Training data: lossy coding adds structured error that a model can learn, and a lossy copy can always be derived from the exact original while the reverse is impossible.
- Per-point structure: labels, per-point timestamps and each point’s place in the scan are indexed by point order, which several point cloud codecs change.
- Sensor calibration and health: calibration and degradation checks measure statistics near the noise floor, which quantization alters.
- Safety and audit: an exact recording can be shown to be what the sensor reported.
- Data infrastructure: content hashes for deduplication, lineage and caching match only on identical bytes.
Lossless here means bit-exact: every declared field listed in section 2 decodes to exactly the bytes that were recorded. For coordinates this is a strict requirement, because they are stored as 32-bit floats and even tiny rounding changes their bits. Rounding the x coordinate of a point about 12 m away to 0.1 mm, a tenth of the millimetre step in which the sensor reports range, still changes 4 of the lowest 6 bits of its 32-bit float [5] (Figure 4). Exact storage therefore costs more than lossy storage, and the rest of this report is about reducing that cost.
- sign
- exponent
- mantissa
Details
For points 8 to 16 m away, 0.1 mm rounding changes a median of 4 bits, all within the lowest 6. Nearer points change more bits, because float spacing gets finer toward zero.The scan as an image
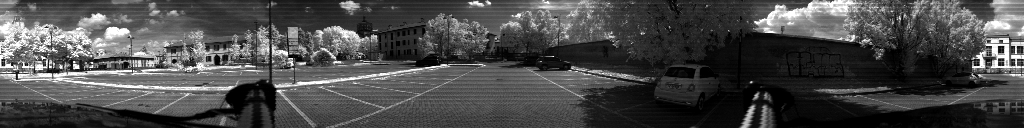
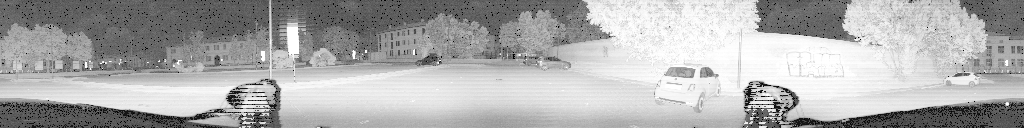
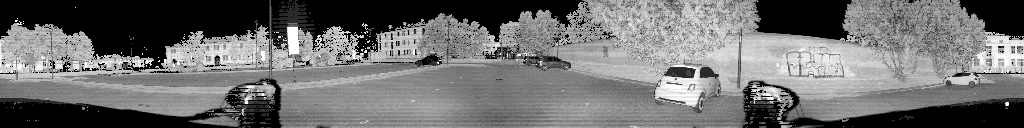
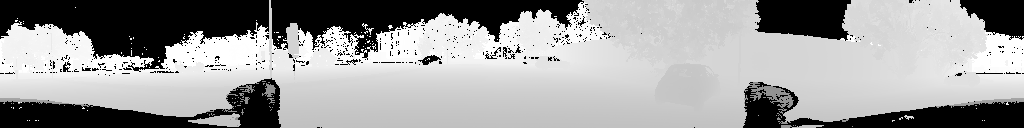
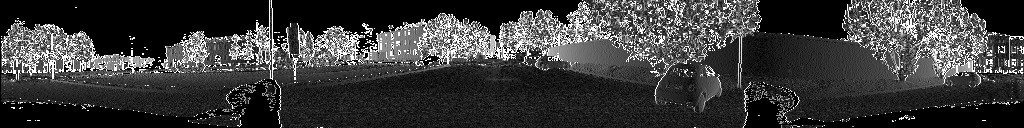
A spinning lidar fires 128 beams at fixed elevation angles, 1024 times per turn. Every measurement therefore has a row (the beam) and a column (the firing), and the sensor reports them in that order. Laid out on this grid, each channel becomes an image of 128 × 1024 pixels: a range image [6, 8]. The images of one scan are aligned, so pixel (r, c) in every channel describes the same laser return.
Because neighbouring pixels on this grid usually see the same surface, a codec that follows the grid can predict each pixel from neighbours it has already decoded, and most of the gains described in this report build on that property. In practice the grid has three imperfections: the vehicle moves while the columns of one turn are fired, so they are measured from slightly different positions; beams that hit sky or absorbing surfaces return nothing and leave invalid pixels; and Ouster sensors stagger their beams in azimuth, so each row of a raw column must be shifted to align with its neighbours [8]. Each of these breaks the smoothness that prediction relies on, so the codec has to handle them explicitly.
Prediction from neighbours
Road, walls and vehicle bodies are locally smooth, so neighbouring returns from the same surface differ in range by small, predictable amounts. The codec exploits this the way lossless image codecs do [1, 2]: it predicts each value from neighbours it has already decoded and stores only the residual. The decoder makes the same prediction and adds the residual back, which keeps the reconstruction exact.
Prediction narrows the range of values the coder has to represent: raw ranges in a scan spread across 60 m, while residuals from the left neighbour cluster tightly around zero (Figure 6). The entropy coder, the stage that turns values into bits (we use rANS [3]), spends few bits on values near zero and more only on the rare large ones. Prediction fails where the scene is not smooth: at depth edges between objects, in foliage, on glass and on wet or reflective surfaces. Those pixels keep large residuals, and the later ideas in sections 7 and 8 target them with better predictors and contexts, the nearby already-coded values that select which statistics the coder applies.
Details
The outermost bars also hold values beyond the axis.Existing point cloud codecs
Several established formats already compress point clouds: MPEG G-PCC [9–11], Draco, PCL’s octree coder and PCD format, LAZ and COPC [12], E57, cloudini, meshoptimizer [25], the ROS 2 point_cloud_transport plugins [26], Jiffy [24], and the sensor vendor’s own format, Ouster OSF, and each of them was built for a different job. G-PCC, Draco and PCL’s octree coder serve streaming and rendering, where geometry is snapped to a fixed grid before coding and the order of the points carries no meaning, and meshoptimizer compresses vertex buffers for real-time graphics. LAZ and COPC come from aerial survey, where coordinates are stored as scaled integers. Apart from OSF and Jiffy, which code the scan grid, and G-PCC’s angular mode, which uses the sensor’s beam geometry, all of them treat a cloud as a set of points and ignore the grid the sensor scanned it on.
When the data has to stay exact, with no rounding of coordinates, these tools reach a compression ratio, declared field bytes divided by compressed bytes, of between about 1.3× and 2.6× on this data. The two strongest lossless options are close: meshoptimizer’s vertex codec followed by zstd reaches about 2.6×, and OSF, which stores each field as an image of the scan grid, reaches about 2.6× with its ZPNG level 9 encoder and the localization cloud coded by pcodec. The point cloud codecs that go higher all do so by rounding coordinates: at 1 mm, cloudini reaches about 4.7×, and G-PCC with angular coding, which is built for spinning lidar, reaches about 4.6× on the lidar scans and returns the points in a different order. PCL’s octree coder reaches about 3.8× and also drops duplicate points. LatentWorlds reaches about 5.1× with every bit and the original order kept, because it predicts along the scan grid and codes the float values exactly.
General-purpose compressors go further on the same bytes but stay below 3×. The strongest, zpaq at its highest setting, reaches about 2.9×, and JPEG XL coding the coordinates as float images [27], OpenZL with a record description trained on a held-out window [29] and WebP lossless [28] all reach about 2.8×. The compression built into ROS 2 tools sits below these general-purpose compressors, with rosbag2’s zstd option [23] and the point_cloud_transport plugins reaching about 1.4× to 1.5×. Learned codecs and the full list of compressors are covered in Data and method.
The comparison below shows compression ratio only, although encoding and decoding speed matter as much for a recording pipeline and often trade off against each other: a codec can spend more work at encode time to make decoding cheap, or the reverse. Section 11 gives the speed of LatentWorlds, and a future post will cover speed and its optimization in detail.
Details
The baselines compress each message on its own; LatentWorlds codes the data as one stream and carries learned probabilities from frame to frame. Lossy rows show the largest coordinate error. G-PCC codes positions and one attribute; the other fields are added with zstd.How the design came together
Recordings usually reach storage already compressed with zstd, so zstd is our baseline. The recording we received was written with zstd chunks, which reduce it from about 480 GB to about 270 GB per hour of driving, about 1.8× on the whole recording and about 1.7× on the lidar’s declared field bytes. zstd is also the default chunk compression of the MCAP Python and C++ writers and of the mcap command-line tool [22]. ROS 2’s MCAP storage plugin writes uncompressed chunks unless a zstd preset is chosen [23]. The baseline in Figure 8, zstd at level 19 on each message, reaches about 1.8×, slightly above the recording as written.
The first stage replaced general-purpose compression with the range-image design, which codes organized scans as aligned images with spatial prediction and an adaptive entropy coder and raised the ratio to about 4.0×. Twelve refinements to predictors, contexts and the fallback compressor followed, each kept because it raised the ratio, and together they brought the codec to about 4.4×. The second structural step, ray-coupled prediction, models how prediction errors follow the laser’s geometry and raised the ratio to about 5.0×. A last series of refinements, mostly in contexts and in how the entropy coder adapts, took it to about 5.1×.
Over the course of this work we tried more than 100 ideas, and many did not hold up at scale, did not help in practice or were not efficient enough to keep. This section follows 49 of them, and 27 are part of the final codec; Figure 8 shows these steps on one scale, together with the ideas we dropped. Most dropped ideas did not change the ratio, typically because the codec chooses the best of several methods per frame and the new method was never chosen. A few made it worse, usually because their side information cost more than it saved.
A gain measured when an idea is added is relative to the codec at that moment, and a later idea that exploits the same redundancy leaves the earlier one less to take. Removing each piece from a near-final build shows the effect: several pieces that added 1–3% when introduced now contribute 0–0.1%, so each idea has to be judged inside the current design.
Details
Each bar starts where the previous step left the ratio, and some steps combine several ideas. We measured the later refinements one at a time. We measured the first twelve together and split their combined gain in proportion to each one’s gain when added, so their individual steps are an estimate. Gains are shown as ranges because exact values depend on the data.Why it works
Each of the ten ideas below works because it matches a property of the data: the way prediction errors follow the laser ray, the way the channels of one pixel see the same surface, or the way static parts of a scene repeat from frame to frame, and the cards below explain each of them in turn.
Ray-coupled cross-axis prediction
+10–15%A predicted point misses along the laser ray (median 23 mm) and barely across it (0.75 mm).
So code one axis, recover how far along the ray the point sits, and predict the other two from there.
Run-aware geometry
+1–3% when addedThe localization cloud has no grid, but 95.6% of consecutive points step exactly one azimuth column (of 1024) around a fitted sensor origin.
Split it into runs and predict each point from earlier points in its run, restarting at run boundaries. Each axis takes context from the axes already coded for the same point.
Adaptive signal coder
+1–3% when addedSignal is coded with an adaptive model that takes its context from the other channels of the same pixel.
All channels of one pixel see the same surface.
Cross-channel context
+1–3% when addedNear-infrared and reflectivity take their context from how well signal was predicted at the same pixel.
At edges, when one channel's prediction misses, the others usually miss too.
Classified least-squares corrector
+0.5–1%Corrects the spatial prediction with a weighted sum of decoded neighbours and previous-frame values. The weights are fit per class of pixel on frames already decoded.
Encoder and decoder fit the same weights, so it costs zero side bytes.
Residual magnitude context
+0.5–1%Coordinates are coded as differences of float32 bit patterns, and float spacing depends on magnitude: finer near zero, as for ground-level z.
The same error in millimetres gives very different bit-pattern residuals. Using the predicted value's magnitude as context lets the coder expect that.
Previous residual context
+0.1–0.5% when addedThe last residual in the run predicts the size of the next one, because errors cluster on edges and rough surfaces.
Temporal-difference context
+0.1–0.5%How far the previous frame's pixel was from its own prediction tells the coder how predictable this spot is.
Static parts of the scene change little from frame to frame.
Adaptation speed
+0.1–0.5%, in two stepsThe entropy coder (rANS) keeps adaptive symbol counts. They now grow faster, are halved sooner, and the coding tables are rebuilt more often.
The models now follow changing data within a frame.
Nearest-neighbour distance context
+0.1–0.5%A k-d tree of already decoded points is queried with the prediction. The distance to the nearest decoded point becomes context: dense areas give small residuals.
Offline it explained 4 to 7% of residual entropy per axis.
The localization cloud
The two lidar topics compress at very different ratios, and the localization cloud’s coordinates now take more than half of the output (Figure 10). The difference comes from how the localization cloud is produced: its points are motion-corrected and their scan order is removed, so a point no longer has known neighbours on a grid. Because prediction depends on neighbours, the codec has to recover them first. We found that 95.6% of consecutive points still step exactly one azimuth column around a fitted origin, which lets the codec rebuild runs of points and predict along them, although these runs remain a weaker basis for prediction than a true scan grid.
The coordinates of the lidar scans take no space of their own in the output, because each point’s x, y and z follow from its range and the fixed direction of its beam. The decoder rebuilds them from range and the sensor’s beam table, which is stored once, and the result matches the recorded floats bit for bit.
- Localization xyz56%
- Localization intensity and label4%
- Lidar scan near-infrared15.6%
- Lidar scan signal15.2%
- Lidar scan range, time, ring6.4%
- Lidar scan reflectivity2.8%
- Lidar scan xyz0%
Details
Shares are approximate, from per-stream sizes. Topic totals are exact.Redundancy between streams
A codec that sees one message at a time cannot use redundancy between topics, and robot recordings contain a lot of it. The localization cloud is built from raw scans a few frames earlier, transformed by the vehicle pose; intensity fields are often copies or rescalings of reflectivity; and the poses themselves describe how one cloud maps onto another. Physically, these streams record the same laser returns, so most of their information is already in the recording.
A codec that knows these relationships can store the source once and rebuild the derived stream from it, keeping only what the derivation does not explain. This depends on knowing the team’s processing stack, such as which transform and filter produced the derived cloud, so the design is specific to that stack. We have not yet measured the effect on a full recording.
How well it generalizes and what it costs
A codec developed on a short stretch of one recording can fit that stretch too closely, so the real test is data it has never seen. A fleet also needs the codec to run fast enough, and in little enough memory, to keep up with the recordings.
To answer the first, we coded ten later windows of the same length, each as a fresh stream with nothing carried over from earlier data, and then the whole drive, and every one of them decoded bit-exactly. The whole drive compresses to about 5.2× (Figure 12), in line with the tuning window, with the lidar scans at about 8.0× and the localization cloud at about 3.1×. Taken together, the ten windows compress to about 5.2×, while the strongest general-purpose compressors on the same windows stay near 2.8× (zpaq, JPEG XL and kanzi).
about 5.1×
about 5.2×
Details
Each dot is one window with the tuning window’s length, coded as a fresh stream with no state carried in from earlier data.Two public Ouster recordings are a harder test [30, 31]. On 100 scans from a static calibration scene recorded with a 32-beam OS1-32, the unchanged codec reaches about 3.8× against about 4.1× for zpaq; on 25 scans from a 128-beam OS1-128 mapping recording it reaches about 2.9× against about 3.1× for JPEG XL, and every result decodes bit-exactly. We have not yet investigated the gap in detail, but the likely factors are field layouts the codec was not developed on, such as intensity as a 32-bit float, an ambient channel and an 8-bit ring, and, for the calibration recording, a static scene that suits general compressors with long windows.
The design comes with three trade-offs, the first of which is that the range-image approach applies only to organized scans, so the localization cloud needs a separate path (section 9). The second is that carrying learned probabilities from frame to frame improves the ratio but means a frame can be decoded only together with the frames before it, so random access works at the granularity of a coded segment. The third is speed: running on close to one core, the codec decodes lidar scans at about 33 MB/s and encodes them at about 9 MB/s. Encoding the localization cloud is slower, at about 0.6 MB/s, and accounts for about 89% of encode time, which makes it the throughput bottleneck as well as the largest remaining cost (section 9). Over both streams, encoding runs at about 1.5 MB/s and decoding at about 5.6 MB/s, with about 300 MB of memory to encode and 215 MB to decode.
For a deployment, this means the ratio held across the drive the codec was developed on and has yet to be established for other sensor configurations, while encoding speed decides where compression runs. At these rates one core cannot keep up with a lidar’s roughly 55 MB/s of declared fields, so real-time encoding needs parallelism across frames or streams, which section 12 returns to.
Storage at fleet scale
To see what these ratios mean for a fleet, start from one lidar. It produces about 90 MB/s of uncompressed message data, or about 320 GB per driving hour, of which about 55 MB/s is the declared field data a codec has to keep; the rest is padding and message framing. The calculator scales the lidar and camera rates linearly with fleet size and hours driven, and shows lidar uncompressed, with the recorder’s zstd and with LatentWorlds.
- Lidar
- Cameras (JPEG)
| Uncompressed | With LatentWorlds | Saved | |
|---|---|---|---|
| Lidar | ~190 PB | ~23 PB | ~170 PB |
| Cameras (JPEG) | ~39 PB | ~4.9 PB | ~34 PB |
Details
The ratio of the recorder’s zstd is measured on the sample file the recorder wrote, on the same declared-field basis as LatentWorlds. Lidar rates are one lidar scan stream plus the localization cloud derived from it. The LatentWorlds camera codec is the SDK’s H.264 path at its default settings, which is lossy. Radar and logs are not included.Summary and outlook
On this recording, the codec stores lidar data losslessly at about 5.1× on declared field bytes (5.2× over the whole drive), against about 1.7× for the recorder’s zstd chunks and 2.6× for the strongest exact point cloud codec, so one 128-beam lidar’s 199 GB of declared fields per driving hour take about 39 GB, where the recorder’s compression leaves about 117 GB. Most of the gain comes from modelling how the sensor acquires data: the range-image design took the ratio from about 1.8× to 4.0× and ray-coupled prediction from 4.4× to 5.0×, while each refinement added at most a few percent, and some lost most of their value once later steps removed the redundancy they had modelled (Figure 8).
At about one fifth of the declared size, the exact recording can remain the single reference for replay, testing, training and audit, with lossy copies derived when a consumer needs them. Compression also sets how much data can leave the robot, since one lidar’s 55 MB/s of declared fields, about 440 Mbit/s, is well above what a typical cellular uplink sustains, while on the robot it competes with perception and planning for CPU time and battery. A data platform should therefore choose the codec and its settings per stream, sensor model and customer, and adjust them while recording, running a light mode on the robot when CPU or power is the constraint and the strongest lossless coding later at ingest.
Encoding speed is currently the main limit for running the codec on the vehicle. Running on close to one core, it encodes lidar scans at about 9 MB/s and the localization cloud at about 0.6 MB/s, and decodes the scans at about 33 MB/s, so keeping up with one lidar in real time would take about 4 cores for its 37 MB/s of scans and about 29 more for the 19 MB/s of the localization cloud, while lz4 needs a small fraction of that and reaches about 1.2×. We are parallelizing encoding across frames and streams, and coding the localization cloud relative to the scan it was built from, which is aimed at both its slow encoding and its share of the output: over the whole drive it compresses at about 3.1× against 8.0× for the lidar scans, and on the tuning window its coordinates make up about 56% of the compressed bytes.
The design also assumes a spinning lidar with a regular grid of beams and firings. Solid-state and non-repetitive scan patterns have no such grid and need a different notion of neighbours, dual-return configurations add a second value per pixel that is strongly related to the first and should be coded with it, and field layouts differ between sensor models and vendors: on the two public recordings in section 11, made with other Ouster models and field layouts, the unchanged codec trails the best general-purpose compressor. We are testing the codec on more recordings, scenes, weather and lidar models to establish how far the gains carry over, and lossy modes with a bounded error and prediction models trained on a fleet’s own recordings can raise the ratio further.