Data Engine for Physical Intelligence workflows
Solving Physical Intelligence through scale
PRODUCTION MODULES
Production Modules for Physical Intelligence at scale
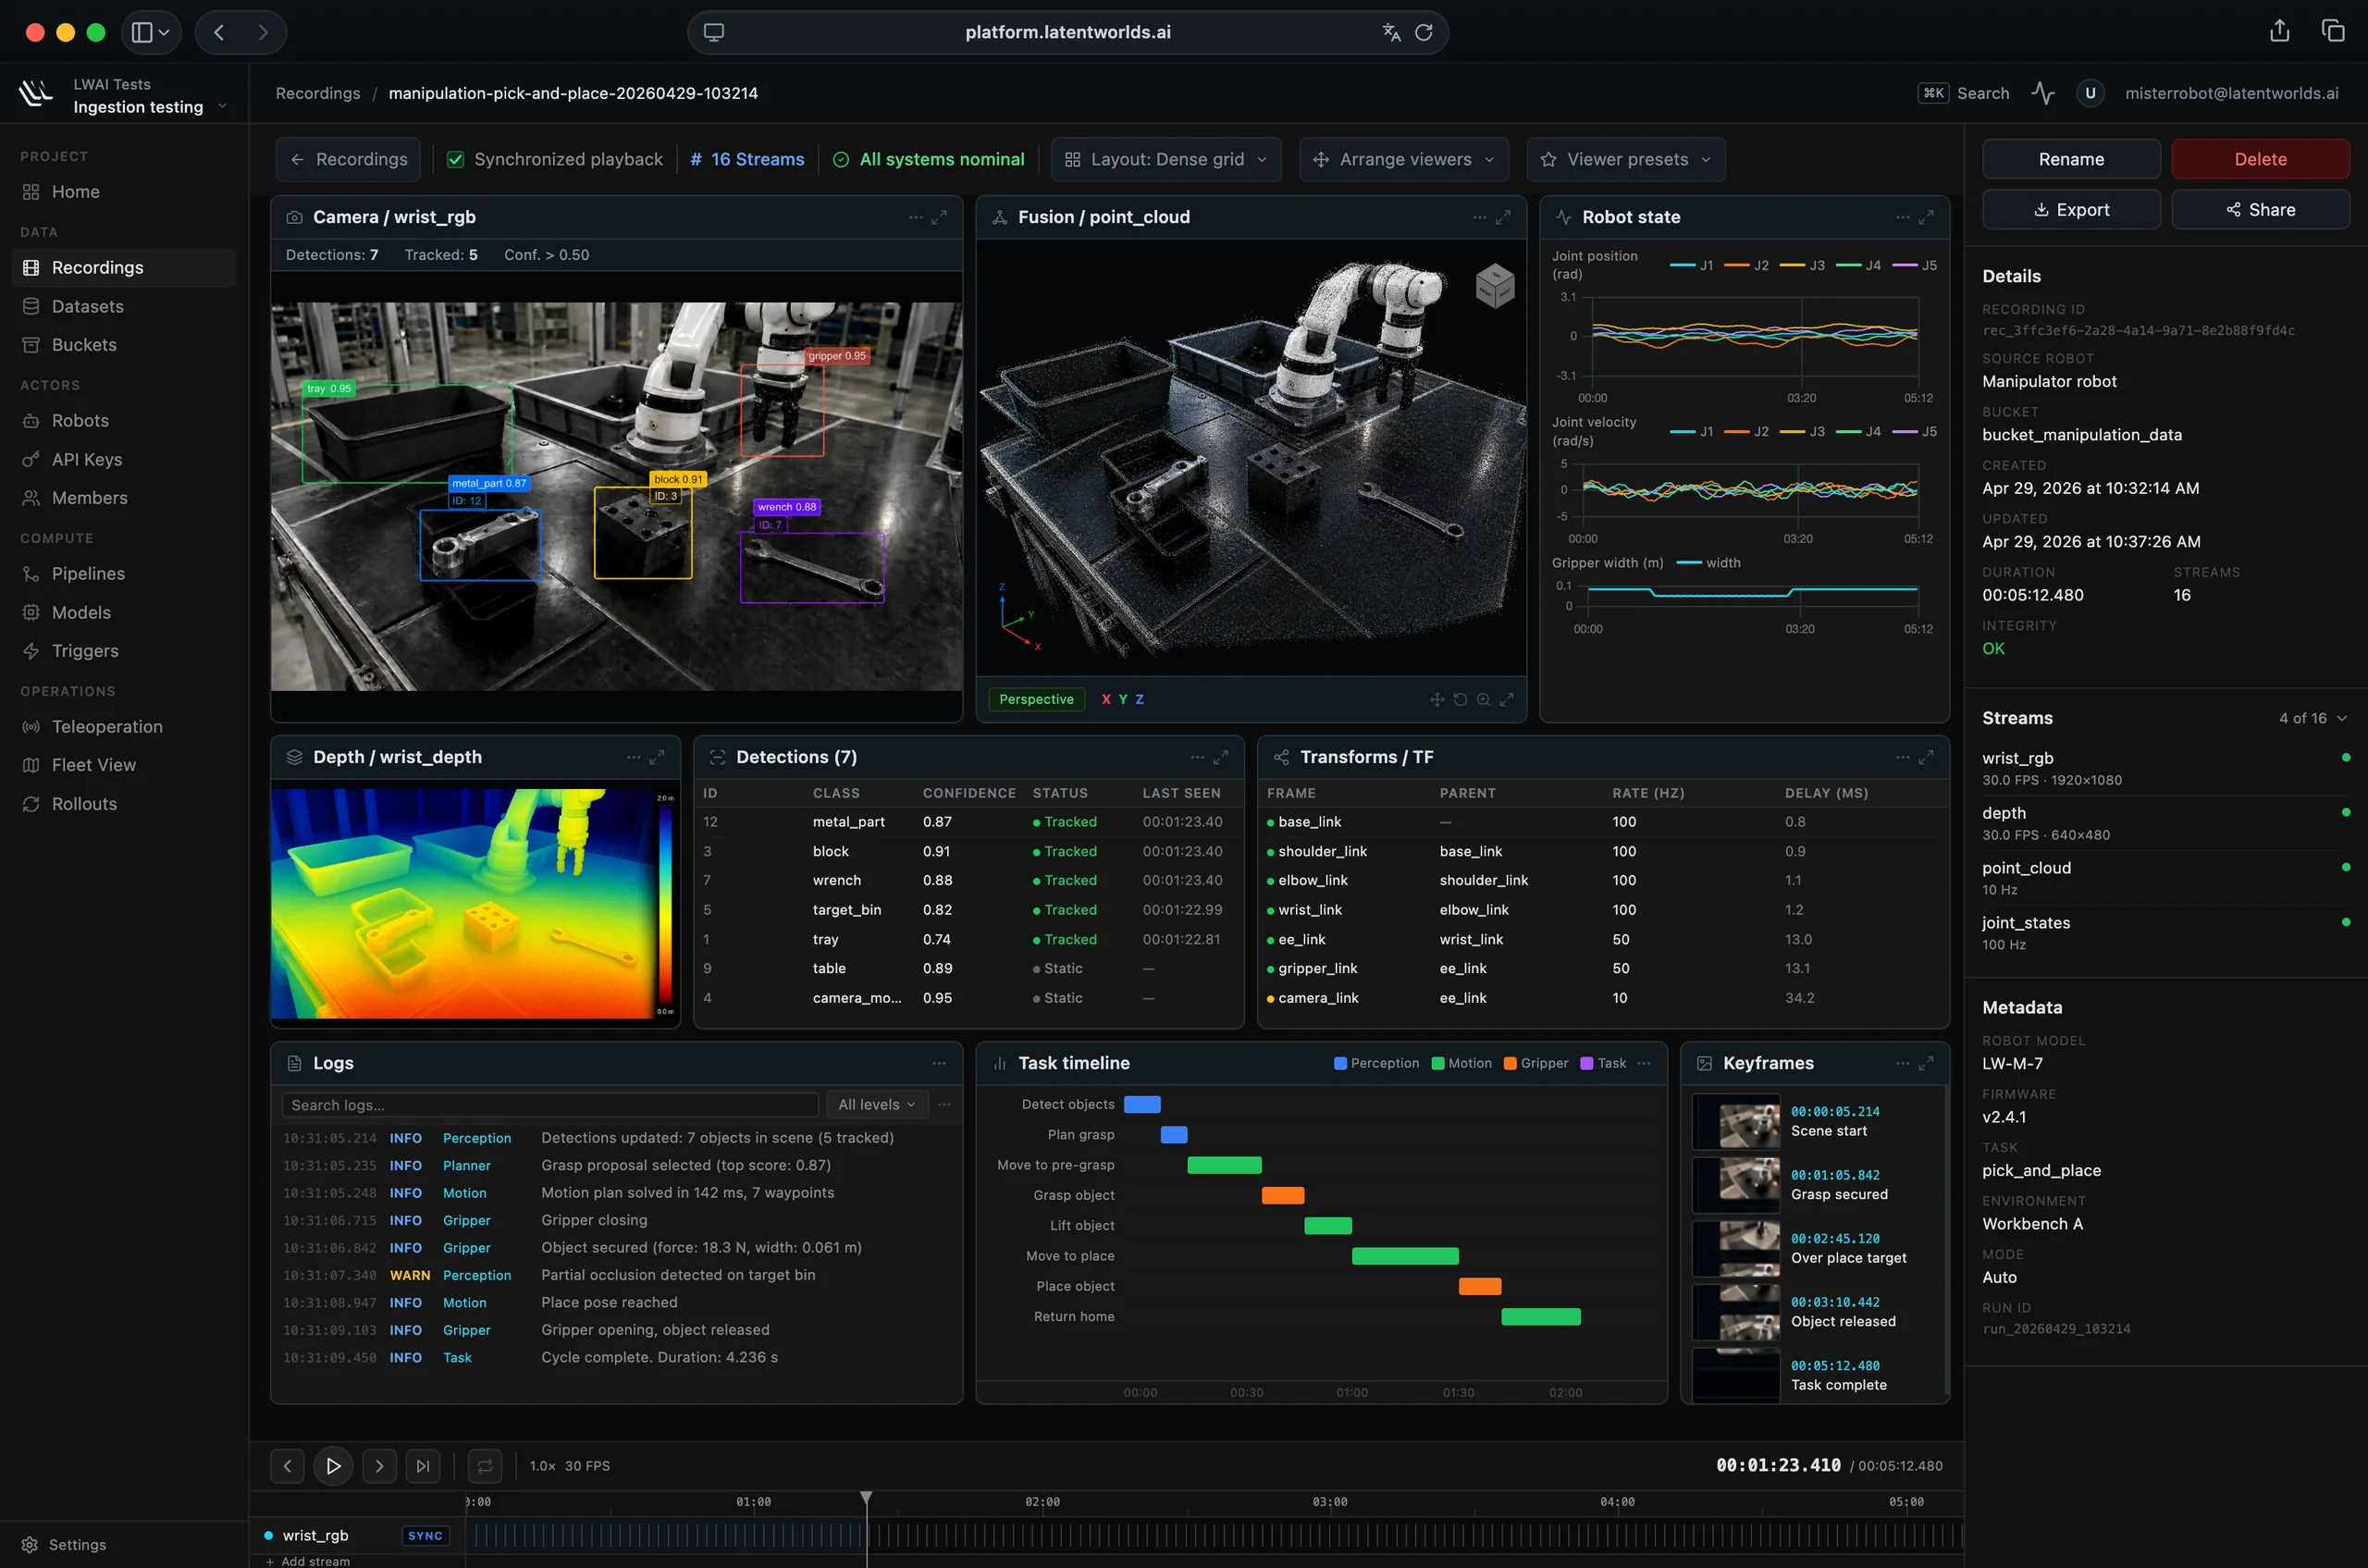
A set of libraries to build and scale your end-to-end multimodal data workflows. Designed to be integrated and deployed within your existing stack, not to replace it.
Ingest, manage, and query multimodal data efficiently at scale. Caudal combines production data infrastructure with annotation pipelines for physical AI applications and model training.
Our Mission
Solving Physical Intelligence through scale.
The gap between model performance and market demands is still far from being closed, with data availability and infrastructure as the main bottlenecks. Our goal is to boost the model development cycle for every company in the space by providing building blocks that easily integrate with any existing stack.
We built every module around the following principles:
- Existing infrastructure should be enriched, not replaced.
- Data shouldn't leave your own network unless you want it to.
- Agnostic by design: any robot, data schema, or deployment stack.
- Petabyte scale should be the norm, not a privilege.
DATA WORKFLOWS
Solving Physical Intelligence through scale
Data corpus size and model iteration speed are the only metrics that matter. The most successful teams are the ones able to quickly iterate on model design, dataset creation, and downstream task evaluation. To support MLOps teams in these objectives, we designed a set of modules that can be easily integrated within an existing data stack.
Run continuous data collection in the wild with resumable uploads and optimal edge buffering. EdgeRelay organizes incoming streams into an optimized cloud storage layout, enriching existing indexes during upload.
Optimize retrieval of queried episodes at petabyte scale. Recordlake serves synchronized data to applications and creates datasets from queries over the stored recordings. Available hosted or customer-hosted.
TRUST
Production-level security and control
LatentWorlds enforces access control at the organization and project level, with defined roles, encrypted API traffic, and device authentication. Our multitenant architecture ensures that data is accessible only within the containing project and through fine-grained permissions.
Boundaries
- Org and project-level access isolation
- Separate identities for people, services, robots, and edge nodes
Access
- Role-based access control with per-project API keys
- Mutual TLS for all robot and edge-node ingestion
Audit
- Audit logs for recordings, exports, incidents, and system changes
- Configurable retention, deletion, and export policies
Data
- Default managed cloud storage, or customer-hosted for full data ownership
- Strict ownership and workflow separation for data in transit
About
The missing layer of the robotics stack
There is no gold-standard infrastructure for turning sensor data into intelligence reliably and at scale. Every robotics company builds their own ingestion, their own storage, their own pile of data-wrangling scripts. It takes years and it eats tons of engineering resources.
We are building that infrastructure. Our data engine makes petabyte-scale sensor data cheap to store and fast to work with, with advanced ML tooling that automates turning raw recordings into training-ready datasets. We support on-premise deployments and a high degree of customization.
Our team comes from

PILOTS